How to Build an Automated Pricing Algorithm
by Dr. Phil Winder , CEO
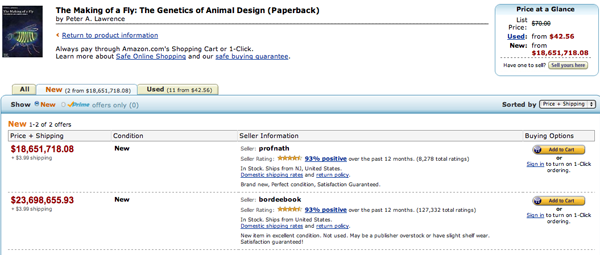
In April 2011, a developmental-biology textbook about flies was listed on Amazon for $23,698,655.93, plus $3.99 shipping. Two booksellers’ pricing bots were pricing against each other. One set its price at 0.998 times its rival’s, the other at 1.27 times the first. The two rules multiply to more than one, so the price ratcheted up daily until a biologist noticed.
You can build a pricing algorithm that would never ask $23.7 million for a biology textbook. The common two-stage build, where you train a model to predict demand and then charge the price the model likes best, is no protection at all. What works is sequential decision making: dynamic programming and reinforcement learning, the ground I have spent most of the last decade on and wrote O’Reilly’s book about.
What is price optimisation?
Price optimisation has a precise textbook meaning: find the price that maximises profit, not revenue. The difference matters, so imagine you run a coffee cart. To sell more cups you must drop the price, and the new price applies to every cup you sell, including the ones already going out, so each extra cup brings in a little less than the one before. Economists call that shrinking gain marginal revenue. Each extra cup also costs you something to make: beans, milk, the cup itself. That is marginal cost. While the next cup earns more than it costs, sell it. The moment it does not, stop. The best price sits exactly at that point, where marginal revenue equals marginal cost. Cost sits in that rule from the very first cup.
How far above cost can you price? That depends on how much your customers care. Commuters queuing outside a station at 7am will pay almost anything for a flat white. Tourists strolling past five rival carts will walk ten metres to save 20p. Economists measure that fussiness as elasticity, and the inverse elasticity rule turns it into a markup: (P − MC)/P = −1/ε. The less price-sensitive your customers, the bigger the markup the market will bear.

“Charge as much as possible to as many people as possible” is the framing that comes naturally, and it is wrong twice over: the highest price and the most customers sit at opposite ends of the demand curve. The version that holds is price discrimination, where you charge each customer their own price, which means charging low-valuation customers less and serving everyone whose willingness to pay clears marginal cost. Price discrimination needs three things: market power, information about each customer’s willingness to pay, and no resale. An automated pricing algorithm is an attack on the second requirement.
(Microeconomics gives you those curves. Econometrics is the business of estimating them from data, and that second word returns when the machine learning arrives.)
Concerts, heatwaves, and bots at war
The smooth textbook curve does not survive contact with the market. Events shift it wholesale. The studied case is an Ariana Grande concert at Madison Square Garden in March 2015: Uber’s own data shows app opens spiking to four times baseline, surge pricing running between 1x and 1.8x for over an hour, driver supply rising up to twofold in response, and average waits holding at 2.6 minutes. The counterfactual came free on New Year’s Eve 2014, when the surge algorithm switched itself off across New York for 26 minutes and the trip completion rate collapsed. Uber wrote the paper, so read it as the vendor’s account.

Heatwaves do the same to electricity. During the July 2026 heat wave, ERCOT’s hourly peak load set a record of 91.1 GW, 6 per cent above the previous record. Coca-Cola discovered in 1999 what happens when you chase that shift too nakedly, with a vending machine that raised prices in hot weather. “It is fair that it should be more expensive,” said CEO Douglas Ivester. The public disagreed, loudly, and the machine died.
A concert or a heatwave shifts a still-smooth curve over time. The clean evidence for genuine kinks is behavioural. Take left-digit bias: scanner data across 3,500 products and 25 US chains shows customers react to a one-cent rise off a 99-ending price as if it were a rise of more than twenty cents, a kink at every dollar boundary, and firms that misprice against it forgo 1 to 4 per cent of gross profit. Shifts come from events. Kinks come from people.
Competition warps the curve a third way. A single firm never faces the market demand curve. It faces residual demand: the market curve net of rivals’ responses. When the rivals are algorithms, the distortion gets strange. The fly book was two locally sensible rules compounding. In simulation, Q-learning pricing agents consistently learn to hold prices above competitive levels without ever communicating. In German retail petrol, when both stations in a duopoly adopted algorithmic pricing software, margins rose 28 per cent. Regulators have noticed: the US DOJ sued RealPage alleging its rent-recommendation algorithm pooled landlords’ private data, a case later settled with conduct remedies and no admission of wrongdoing, so read it as an allegation, not a finding.
The optimiser, when you know the curve
Despite the distortions, pricing against a known demand model is a solved problem. It has a name, dynamic pricing and revenue management, and a standard textbook. The simplest case is fully closed-form: a monopolist facing linear demand computes marginal revenue falling at twice the demand slope, sets it equal to marginal cost, and reads off the price. That is the first runnable demo.
It goes further than you might expect. In 1994, Gallego and van Ryzin derived the optimal finite-horizon pricing policy in closed form for an exponential demand family, and proved that a well-chosen fixed price is asymptotically optimal as volume grows. Every method below has to beat a constant.
Every closed form above assumes a known demand model, a monopoly, and customers who do not strategise. The optimum you compute is optimal for the model, not for the market. So I build a simulator instead. In a simulator the model is the market, and you can measure exactly how wrong each method is.
Fit the curve with ML, fall into the trap
When you have data, the modern move is two-stage: train an ML model to predict demand, then run an optimiser over its predictions. This is deployed at scale. Airbnb runs a booking-probability model with a price-suggestion layer on top, and Lyft estimates rider price-response curves and solves a constrained optimisation over them. But the data is the trap.
Historical pricing data is poisoned by the policy that generated it. Past prices were set in response to demand, because a busy week gets a higher price, so a naive fit learns a confounded demand curve, sometimes even an upward-sloping one, and an optimiser over a biased curve confidently picks the wrong price. The trap has a name, endogeneity, and econometricians have been correcting for it since the early nineties. The fixes are instruments, double/debiased ML, or randomised price experiments. An airline-pricing study shows the size of the hole: direct ML regression misestimated price sensitivity by around 25 per cent, and a debiased two-stage estimator cut that to around 4.


Prediction error and decision error are different targets. Smart Predict, then Optimize trains the demand model against the pricing objective itself.
A product worth pricing
The worked example needs choosing with care. My criteria: a product everyone understands and appreciates, hard physical capacity, so you cannot sell infinitely, and a true cost floor, so you cannot price infinitely low. Hotels meet all three, and we have worked on hotel pricing a lot, including five months testing offline reinforcement learning for Duetto. This time I wanted a different product. Once you look, half the natural candidates are hotels in disguise: airline seats, campsite pitches, ferries, cinema seats and event tickets are all perishable inventory sold over a booking horizon, room-night revenue management wearing a costume.
Take an electric-vehicle charging site. Everyone understands paying to plug in. The capacity constraint is physical twice over, because a site has a fixed number of stalls and a total electrical feed shared between them, and the cost floor is real, because every kWh sold has a wholesale cost. Demand peaks on weekday evenings, varies by location, and spills between neighbouring sites. Tesla is already doing it. It began piloting utilisation-based Supercharger pricing at ten sites in May 2025, with prices responding to live station load (Not a Tesla App). Tesla will not say what the algorithm earns, because Supercharging is buried inside its “Services and Other” revenue line. Within six months it had expanded the pilot to more than 550 sites across five states, claiming lower congestion and higher utilisation at unchanged average prices. A 55-fold expansion in six months suggests it pays, and the win Tesla claims is throughput, not price. The physics does not need inventing either: Caltech’s ACN portal holds real charging sessions and a simulator of the infrastructure constraints, and SustainGym wraps it for RL.
The runner-up was street parking. San Francisco’s SFpark pilot repriced over 6,000 meters from 2011 and hit its 60 to 80 per cent occupancy target 31 per cent more often, cut search time 43 per cent, and dropped average meter rates by $0.11 an hour. Dynamic pricing that lowered prices, and the same throughput story Tesla tells. Its weakness against my criteria is that an empty parking space has near-zero marginal cost, so the floor is policy, not physics. The rest fell out faster. Perishable-food markdowns have a hard expiry and a real floor, but the price only ever falls (Wasteless cut supermarket food waste 39 per cent in pilots). Ride-hailing is canonical but demands a two-sided simulator with driver repositioning. Half-hourly electricity tariffs like Octopus Agile even pay customers during negative-price plunges, but the retailer is mostly a wholesale price-taker, so the algorithm-chooses-the-price story is weak.
Event tickets deserve a note of their own. The UK competition authority investigated the Oasis “surge” and found no real-time algorithm at all, just pre-set tiers at up to roughly 2.5 times face value. The algorithm took the blame when there was not one.
The simulator, one distortion at a time
A workable demand simulator needs surprisingly few parts. The one built for the 2017 INFORMS Dynamic Pricing Challenge used a Poisson arrival process for customers, a segment draw for bargain-hunters, loyal customers and comparison shoppers, a willingness-to-pay distribution per segment, and a logit choice model against the posted prices (van de Geer et al.). Everything else is a knob on one of those parts: seasonality is a time-varying arrival rate, capacity is a cap on units sold per step, competition is other agents posting prices, and dependence between steps arrives with reference prices, because customers remember what you charged yesterday.
So build it progressively, one distortion at a time, and make each step visible in the data. Start with a willingness-to-pay distribution and a posted price, and a smooth demand curve appears. Add a time-varying arrival rate, and the concert and the heatwave appear as spikes (airline data shows the same time-varying arrivals with scarcity effects empirically). Add the capacity cap and the cost floor, and you have the physics of the charging site. Add competitor agents, and you get residual demand and the price spirals of the opening. Add reference prices, where demand depends on the current price and a remembered one, with loss aversion, so rises above the reference hurt more than cuts below it help, and the steps stop being independent. Then add stockpiling, and today’s bargain empties tomorrow’s market, because customers who buy at a discount fill their pantries and stay home afterwards. Macé and Neslin measured that dip across ten product categories and 30,000 products: post-promotion dips give back 22 per cent of the promotion bump, and pre-promotion dips another 11.

I copied two design details from the challenge. Competitors could observe all posted prices but only their own sales, which is a realistic information constraint. And no algorithm won across all market conditions — the overall winner simply fitted a logit demand model. The challenge deliberately omitted inventory to isolate learning under competition, and I am choosing to put capacity back in. The code is on GitHub at winderai/pricing-gym, and the space is oddly green-field: searching in August 2026 I could find no general-purpose dynamic-pricing gym on GitHub. The serious simulators are all domain-specific: ACN-Sim for EV charging, ABIDES for financial markets, SustainGym, and OR-Gym for inventory problems.
When today’s price poisons tomorrow’s demand
Reference prices change the character of the problem. Single point-in-time optimisation fails here because the steps are not independent, so you need a sequential decision-making method. Classical dynamic programming solves small, well-modelled versions exactly (Gallego and van Ryzin). Reinforcement learning is its approximate, model-free descendant, and the thing you reach for when the state space is large or you cannot write the demand model down.
Myopic pricing under reference effects is not merely weaker, it is biased. Managers who ignore the long-term effect of today’s price on tomorrow’s reference point “systematically price too low and lose revenue”. The sequential lineage is also old. Airline revenue management has run sequential, non-RL methods in production since the late 1980s, with Belobaba’s EMSR heuristics reportedly landing within half a per cent of the dynamic-programming optimum. For reference effects specifically, den Boer and Keskin’s policy advice is simple: change prices slowly.

RL earns its place when the model runs out. It has been fielded: a deep-RL experiment on Alibaba’s Tmall repriced thousands of SKUs and beat expert manual pricing. But the survey literature is blunt about the costs: brittleness, sample inefficiency, hyperparameter sensitivity, and no convergence guarantees beyond tabular settings. Real-world price exploration is expensive too, because every experiment is charged to a customer. That is why the simulator exists. Between the extremes sit online-learning algorithms with provable regret bounds even for long-term reference effects.
Generate the data, climb the ladder
Generate two datasets from the simulator, not one. In the first, prices are randomised: clean, exogenous data that no real company possesses. In the second, the simulated seller prices in response to demand, the way every real price log was made. Fit the same model to both, and the endogeneity bias stops being an assertion and becomes a picture, with debiased estimators scored against known truth. Logged-policy data is exactly the offline-RL setting.
Then climb the method ladder as the simulator grows. The first rung fits a parametric demand model, linear or logit, and grid-searches the price, which is what the challenge winner did. The second reaches for flexible ML, gradient-boosted trees (XGBoost in the companion repo) plus an optimiser, and the endogeneity trap bites here. The third is contextual bandits, learning while pricing. The fourth is RL, once reference prices make the steps dependent. Each rung breaks when the next distortion switches on.
The third market in the scorecard below is Black Friday. Retailers run high-low pricing on purpose. Hendel and Nevo showed that a temporary price cut is intertemporal price discrimination: it separates the bargain-hunters who stockpile from the loyal customers who pay full price, and captures a quarter of the gap to perfect discrimination. The discount is often theatre against a managed reference, and Which? found nine in ten Black Friday “deals” were the same price or cheaper at other times of the year. Popescu and Wu supply the theory for both halves of the problem: with loss-averse customers the optimal price converges to a constant, which is why the patient seller above holds steady, but when customers chase the gains, the optimal policy cycles. No fixed price is optimal, and only a method that sees the remembered price can express the winning policy.

The fly book, priced properly
Back to the book about flies. Neither bot was broken. Undercutting your rival by a fraction is sensible, and so is pricing above a cheaper listing you can buy from on demand. Each rule was locally reasonable and blind to the sequence the pair of them were creating (Eisen). The danger was never the algorithm. It was point-in-time thinking. A sequential learner watching its own price history would have priced the fly book like a book.
The other half of the lesson is judgement. Customers punish pricing they read as unfair. The temperature-priced Coke machine died of it, and Ticketmaster took the blame for an algorithm that did not exist. Automate the pricing. Keep the judgement.
Frequently asked questions
An automated pricing algorithm sets prices from data without a person choosing each one. The textbook target is the profit-maximising price, where marginal revenue equals marginal cost, so cost counts from the first unit sold. Real demand shifts with events such as concerts and heatwaves, bends at price points such as 99 cents, and responds to competitors and to the prices customers remember. A working algorithm therefore has to learn demand from data and plan across time as well as optimise a single price.
Historical prices were set in response to demand, so a busy week tends to carry a higher price. A model fitted to that log learns a confounded demand curve, sometimes one that slopes upwards, and an optimiser run over it confidently picks the wrong price. Econometricians call this endogeneity. The fixes are instrumental variables, double/debiased machine learning, or randomised price experiments. In a published airline-pricing study, direct ML regression misestimated price sensitivity by around 25 per cent, and a debiased two-stage estimator cut the error to around 4 per cent. In Winder.AI’s open-source simulator, pricing off a straight-line fit to a log where prices tracked demand captured 45 per cent of the optimal profit, and double ML captured 97 per cent.
Use reinforcement learning when today’s price changes tomorrow’s demand: customers remember past prices and feel rises above that reference more than cuts below it, or they stockpile during a promotion and buy less afterwards. Pricing one step at a time is then biased, and research on reference effects finds that managers who ignore them systematically price too low. When each step stands alone and the demand model is known, a well-chosen fixed price or a fitted parametric model is hard to beat, and dynamic programming solves small, well-modelled problems exactly. RL has real costs: brittleness, sample inefficiency, sensitivity to hyperparameters, and live price experiments that customers pay for. That is why a simulator comes first.
Winder.AI publishes pricing-gym, a small dynamic-pricing simulator with a Gymnasium interface, under the MIT licence. It follows the 2017 INFORMS Dynamic Pricing Challenge recipe of Poisson customer arrivals, customer segments, a willingness-to-pay distribution per segment, and a choice over the posted prices. Seasonality, capacity, a cost floor, competing bots, reference prices and stockpiling are all knobs on those parts, and it ships one agent per method, from a linear demand fit to tabular Q-learning. Searching GitHub in August 2026, we found no other general-purpose dynamic-pricing gym. The serious simulators we found are domain-specific: ACN-Sim for EV charging, ABIDES for financial markets, SustainGym, and OR-Gym for inventory problems.
Pricing algorithms can reach high prices without communicating. In simulation, Q-learning pricing agents consistently learned to hold prices above competitive levels. In German retail petrol, margins rose 28 per cent when both stations in a duopoly adopted algorithmic pricing software. The US Department of Justice sued RealPage, alleging that its rent-recommendation algorithm pooled landlords’ private data. The case settled with conduct remedies and no admission of wrongdoing, so it remains an allegation. Rules that each look sensible can also compound: in April 2011 two booksellers’ bots pushed a biology textbook on Amazon to $23,698,655.93.